Benchmarks
Real tasks, run several times per setup, graded by running the result. Every attempt, cost, and output, including the losses.
One prompt, one run each: a cup of espresso you stir with your cursor, where speed is force. Opus 5.5 against Opus 5.5 with the threejs-tsl Workbench.
- Opus 5.5 Vanilla 1/1
- threejs-tsl pompeii/threejs-tsl on Opus 5.5 1/1
One jet ski game built in three stages by GPT 6.1 Sol, Opus 5.5, and Opus 5.5 with the threejs-game Workbench. Each stage picks up the code the last one left behind.
- GPT 6.1 Sol Vanilla 1/1
- Opus 5.5 Vanilla 1/1
- threejs-game pompeii/threejs-game on Opus 5.5 1/1
One pinball prompt, three attempts each: Muse Wonder, Opus 5.5, and Opus 5.5 with the threejs-game Workbench.
- Muse Wonder Vanilla 3/3
- Opus 5.5 Vanilla 3/3
- threejs-game pompeii/threejs-game on Opus 5.5 3/3
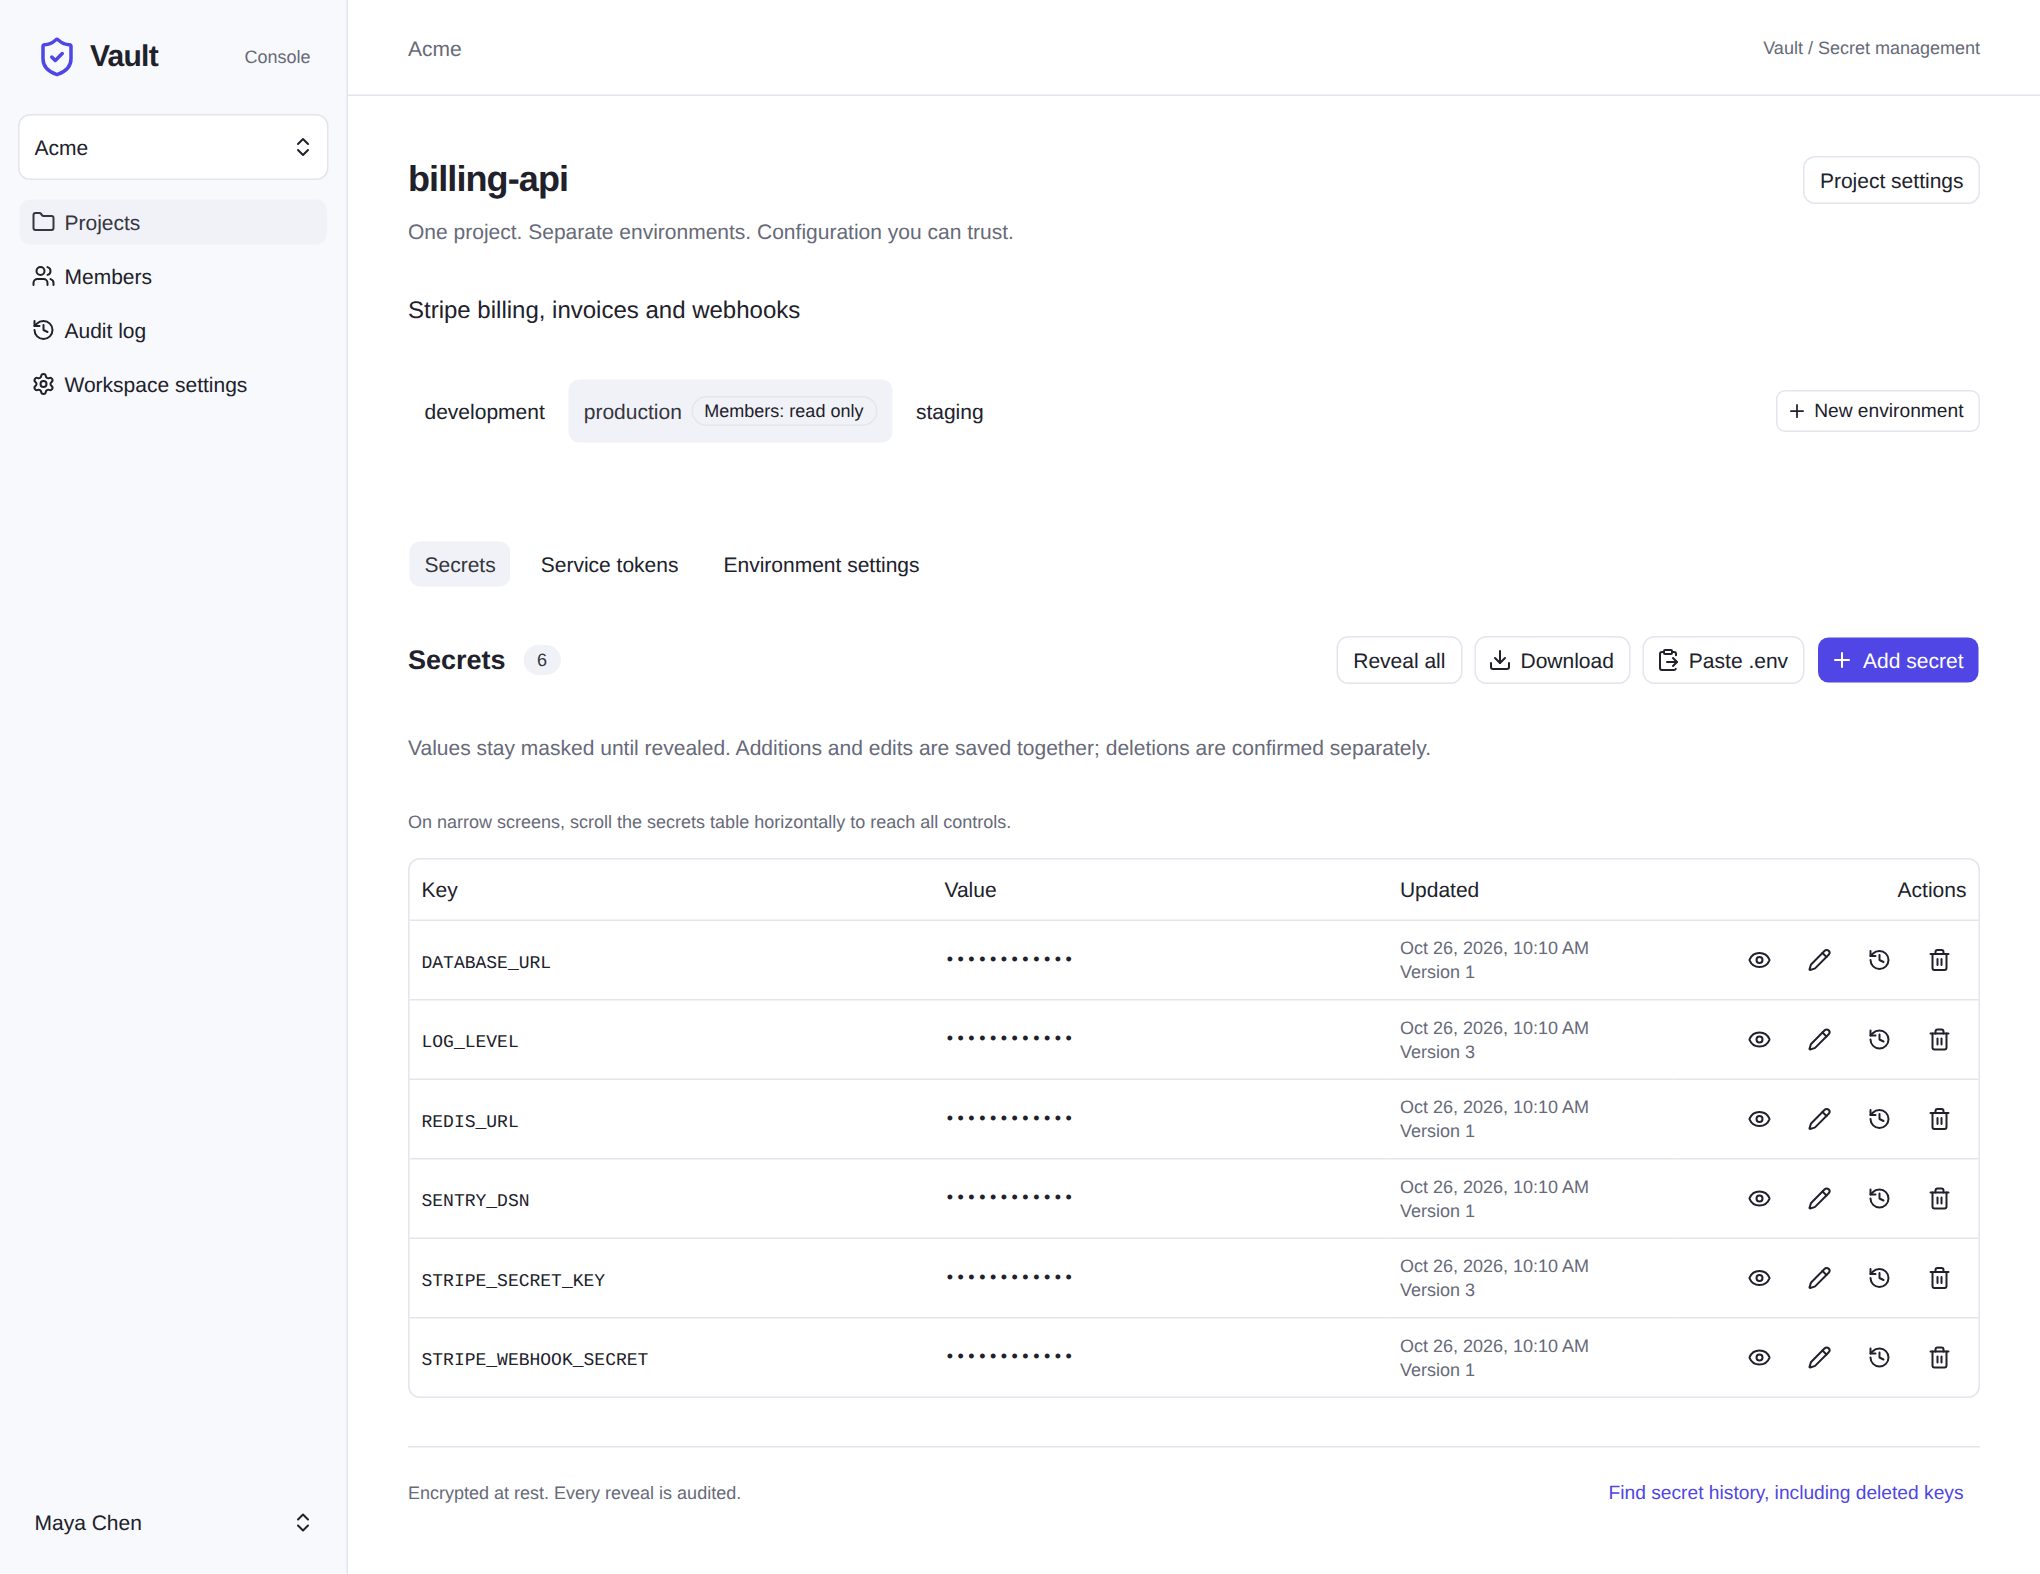
We built a Doppler-style secrets manager from an empty repo with three Workbenches, then hosted it for our own team, fixing the Workbenches as we went. Here's what it cost, how long it took, and how good the result is.
- model cost, every run included $43.70
- Workbench runs, 33 of them building features 61
- total run time, start to finish 16.9 h
36 working results with Workbenches, 20 without, across 8 tasks.